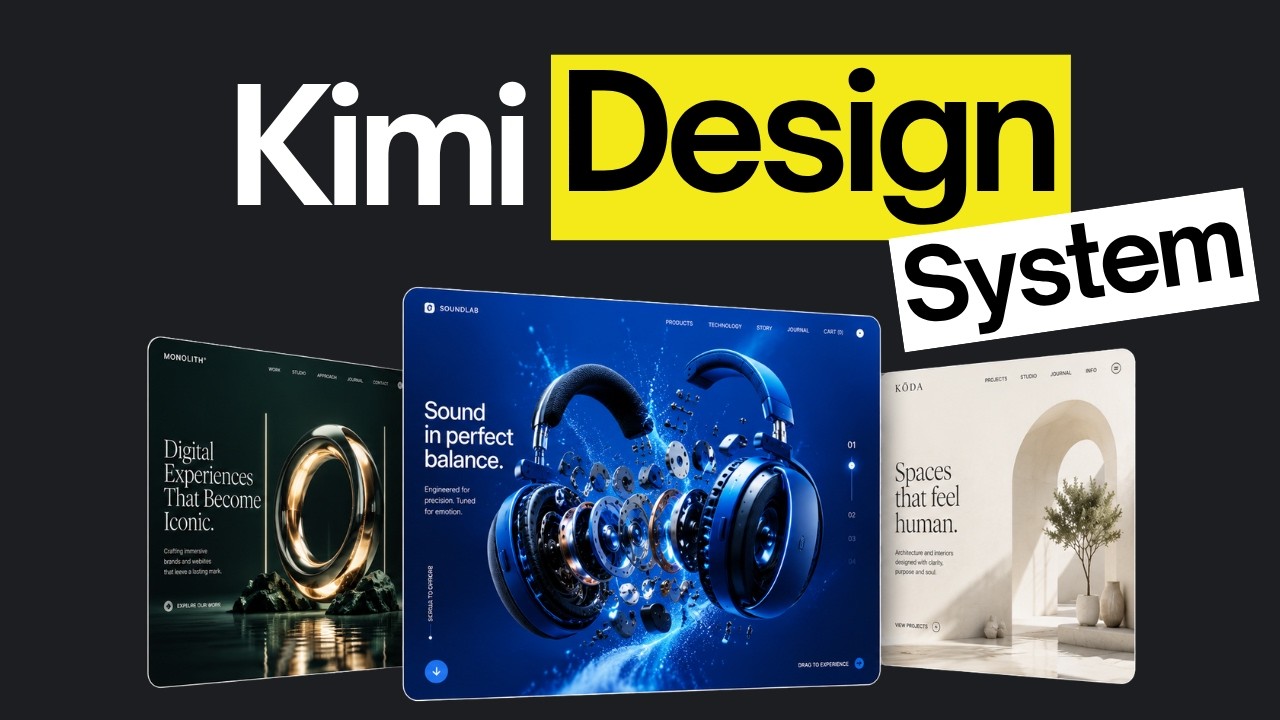
This is the more technical companion to the Jack Roberts "Kimi K3 Just Changed Website Design Forever" video. Less selling, more mechanism. It has one sponsor read (Jolly memory) and a community upsell (AI Labs Pro), separated out below. Install commands shown on screen are transcribed, not run.
What this video is about
Kimi K3 is top-tier and cheap, with a real differentiator. On Artificial Analysis intelligence it scores 57, just behind Fable 5 (60) and GPT-5.6 Sol (59); on LM Arena's web/frontend board it ranks #1 (1678), ahead of Fable 5 (1634) and GPT-5.6 (1630); it is the cheapest of the three at $3/$15 per 1M tokens. Its edge is "vision in the loop": it screenshots what it builds and adjusts, instead of only reading its own code.
Don't use Kimi's own harness. "Kimi Code" is roughly 3x slower (a task that takes Claude Code/Codex ~3 min takes it ~10) because Kimi K3's weights aren't open, so only Kimi's overloaded servers host it, and the harness itself underuses the model and loses context when you switch models.
Run Kimi K3 inside Claude Code instead, via a local CLI-proxy of the subscription you already pay for. The whole trick is four lines: point ANTHROPIC_BASE_URL at the local proxy, pass a local key as ANTHROPIC_AUTH_TOKEN, set ANTHROPIC_MODEL=kimi-k3, run claude. It's session-scoped, so nothing is permanent.
Every model has default design "tells". Opus 4.8 reaches for orange/cream/brown, gradients, rounded boxes, a hero image behind large offset text, and marketing hype words; Kimi inherits Opus's look because Chinese models are often distilled from Claude; Codex defaults to green/white, heavy SVGs, and small fonts. Common "slop": Unsplash stock photos, gradient text, placeholder images.
Hallmark is the fix. An open-source anti-AI-slop skill (Nutlope/hallmark) with four verbs (build, audit, redesign, study), 100+ references, and a 58-check "slop" gate before it hands work back. Tested head-to-head, it made Kimi, Opus 4.8, and Codex each look noticeably more intentional; it currently works best on Claude's own models.
Two caveats that will bite you: when Kimi runs inside Claude Code, auto-compaction doesn't fire, so a full context window makes answers drift generic; and skill auto-invocation is unreliable with Kimi (it's tuned to Claude's models), so trigger the skill manually with its slash command.
Kimi K3, by the benchmarks (0:00–3:02)
Source statementKimi K3 (Moonshot's flagship) is on the same tier as Fable 5 and GPT-5.6, with a 1M-token context window, and is "genuinely good at front end" (0:00–1:31).
Visual evidenceon general intelligence it is a hair behind the two leaders, not ahead of them.
CaptionGeneral intelligence. Kimi K3 (57) sits just behind Fable 5 (60) and GPT-5.6 Sol (59), and clearly ahead of Gemini 3.6 Flash (50) and the rest. Source: 1:35
Source statementon front-end design specifically, it beats even those two, as measured by LM Arena (models run against each other on the same prompt, ranked by real user votes) (1:40). One reason: its built-in "vision in the loop" (2:00).
CaptionFront-end design, blind-tested. Kimi K3 ranks #1 (1678) ahead of Fable 5 (1634) and GPT-5.6 (1630). Source: 1:45
Inferencethe "vision in the loop" claim is the interesting part. Most models predict how a page will look from the code alone; Kimi takes a screenshot of the rendered result and corrects from what it actually sees, which the video credits for its more balanced spacing and layout.
Source statementon price, Kimi K3 is $3 in / $15 out per 1M tokens, versus GPT-5.6 at $5/$30 and Fable 5 at $10/$50 (2:35).
CaptionThe Claude-side anchor for the price comparison (Fable 5 $10/$50). Kimi K3's $3/$15 and GPT-5.6's $5/$30 are stated in narration; on this axis Kimi is the cheapest of the three. Source: 2:05
Why not Kimi's own harness (3:02–3:50)
Source statementKimi ships "Kimi Code", a terminal coding agent launched with their K2.5 model, but it is slow: a task that takes Claude Code or Codex ~3 minutes takes Kimi Code closer to 10 (3:02). Two reasons: Kimi K3's weights aren't open, so every request goes back to Kimi's own (overloaded) servers; and the harness itself is rough, with Kimi's own docs admitting it isn't built to bring out K3's full potential. Two more problems: switching models breaks Kimi Code's context retention (Claude Code and Codex hold context across switches), and its sub-agent behaviour is opaque (it looked like many, but reported only five).
Inferencethe takeaway is not "Kimi K3 is slow" but "Kimi's harness is slow". Put the same model in a better harness and the speed problem goes away, which sets up the next section.
Running Kimi K3 inside Claude Code (3:50–5:20)
Source statementyou can point Claude Code at Kimi K3 two ways. Straight through Kimi's API works but bills you per token; the cheaper move is to run through the Kimi plan you already pay for, using a tool called CLI proxy API that turns the coding tools you're logged into into a local API on your own machine (3:50–4:33). Install with brew install, log in with the Kimi login command, start the server, then generate a local API key (or just ask the agent to do it).
CaptionThe local proxy. CLIProxyAPI wraps your logged-in subscriptions (Kimi, Gemini, Claude Code) into one local API at localhost:8317, so you never touch a per-token bill. Source: 4:30
Source statementthen launch Claude Code with its base URL repointed at that local server, the generated key as the auth token, and the model set to Kimi K3. These settings live only in that one terminal session (4:55–5:20).

CaptionThe entire technique in four lines. Override ANTHROPIC_BASE_URL to the local proxy (port 8317), pass the local key as ANTHROPIC_AUTH_TOKEN, set ANTHROPIC_MODEL=kimi-k3, run claude. Session-scoped: a new terminal is back to normal Claude. (The audit run later shows an alternative base URL, https://api.moonshot.ai/anthropic, i.e. Moonshot's direct Anthropic-compatible endpoint.) Source: 5:15
The Hallmark skill and its four verbs (5:20–6:05)
Source statementany model, left alone, falls back to its safe design patterns, so you need something to push it off the default. Hallmark is an anti-AI-slop design skill for agents, used through four verbs (5:30). It ships a library of design styles, and its recipe.md documents prompting best practices. Its study verb is the clever one: hand it a site you like and it treats that site as a reference rather than cloning it, so your result stays original.

CaptionThe four verbs, from Hallmark's own SKILL.md. default = build new; audit = score against anti-patterns and report (never edits); redesign = fresh visual direction within existing boundaries; study (below the fold) = use a liked site as a reference, not a clone. Source: 11:52
CaptionThe actual project. Hallmark is open source at Nutlope/hallmark (Hassan El Mghari). You install it from here. Source: 6:02
Installing Hallmark and what's inside it (6:05–7:48)
Source statementinstall by pasting the repo's install command into the terminal; it asks which agent to install for. Kimi Code and Codex use the .agents folder; for Kimi-in-Claude-Code you also select Claude Code, which installs into .claude. The SKILL.md carries more than a hundred references (including AI-slop patterns) and runs a 58-gate test (58 checks) before returning output (6:05–7:48).
CaptionWhy it beats a one-page prompt. The skill is a whole reference library (anti-patterns, verbs, themes, components, color, copy) that loads only the parts a given verb needs. Source: 7:48
Kimi's own design tells (9:07–9:40)
Source statementeven though Kimi is good at front end, it has its own patterns, and because Chinese models are often trained by distillation of Claude models, Opus 4.8's style shows up in Kimi's output: images behind the hero, large hero text offset to the side, warm orange/brown palettes regardless of light or dark. The one thing the video prefers about Kimi is that its writing isn't stuffed with the marketing hype words Opus leans on (9:07).
Testing Kimi K3 with the skill (9:40–10:37)
Source statementrun in Claude Code with Kimi, a simple landing-page prompt. It opens with a pre-flight that scans your existing files and decides what to keep versus change, then asks three things (audience, use case, tone) before building; when done it confirms all 58 slop checks passed (9:40).
CaptionWhat the pre-flight actually produces. A JSON scan of the project recording the current font stack, palette, and motion, each with a keep/replace decision and a note on how Hallmark will change it. Source: 10:00
Source statementthe audit verb generates a report against the slop patterns and flags every finding for you to accept (10:37). In their run, after the audit Kimi removed an AI-slop font, swapped Unsplash images to another source (Pixum), and fixed mobile responsiveness.
CaptionThe audit verb's output: a severity-ranked punch list with a plain-English verdict and specific findings ("Fix the font pairing first; it's the one finding that ships as slop"), then a one-tap "run the fixes". Note the base URL here is api.moonshot.ai/anthropic, the direct-API variant. Source: 11:00
Source statement (caveats): because auto-compaction won't run when Kimi drives Claude Code, watch the context window; once full, answers drift off the instructions and turn generic (11:00). And because Kimi isn't Claude Code's default model, automatic skill invocation is unreliable, so invoke the skill manually with its slash command (11:30).
Testing Opus 4.8, with and without the skill (11:52–13:40)
Source statementthey ran the same test on Opus 4.8 both ways. Without the skill it built in ~6 minutes and produced heavy AI slop, classic Opus from the colours to the background gradient to the rounded boxes; their own AI-slop detector flagged it (calling out gradient text). With Hallmark it took longer but came out more creative and intentional, with better button interactivity, and it refused to drop in placeholder Unsplash images because stock imagery is one of its slop rules (11:52–13:20).
CaptionOpus 4.8 without the skill, in its own words: the "sunset over static" coral/flame/violet palette on near-black with gradient cover art, exactly the Opus tells the video warns about. Source: 12:05
CaptionOpus 4.8 with Hallmark. The same model, pushed off its defaults: a restrained editorial palette, purposeful type, no stock-photo filler. Source: 12:45
Inferencethe honest conclusion the video draws is that Hallmark currently works better on Claude's own models than on Kimi, because it flags the known (Opus/Codex) patterns and doesn't yet have a deep model of how Kimi specifically designs.
Testing Codex with the skill (13:40–15:12)
Source statementCodex defaults to green and white, leans on SVGs, and picks small font sizes. Tested with the skill in the .agents folder (using the Codex app for its browser tools), it ran the pre-flight, asked audience/use/tone, edited multiple files, and ran an interactive browser test. The result read as intentional rather than slop; a later Hallmark audit said the structure was strong with only a few issues (mainly responsiveness) (13:40).
CaptionCodex with Hallmark. The blue/white can still read as AI-generated, but here it lands as intentional because it fits a technical product; the embedded dashboard mock is a step above Codex's default output. Source: 14:28
Tools and resources
Tool / resource
Role
Notes
Kimi K3 (Moonshot AI)
The design model under test
1M context; LM Arena web #1; $3/$15 per 1M tokens; "vision in the loop"
Kimi Code
Kimi's own terminal harness
Rejected as ~3x slower; weights not open, harness underuses K3
CLI proxy API (CLIProxyAPI)
Local proxy of your subscriptions into one API
localhost:8317; lets Claude Code run Kimi K3 on your plan, no per-token bill
Claude Code
The harness they run Kimi K3 in
Base-URL + auth-token + model override, session-scoped
Hallmark (Nutlope/hallmark)
Open-source anti-AI-slop design skill
4 verbs, 100+ references, 58-gate slop test; installs to .agents/.claude
Artificial Analysis
Intelligence benchmark cited
Kimi K3 = 57
LM Arena
Front-end design leaderboard cited
Kimi K3 = #1 (1678)
Jolly memory
Sponsor (not endorsed here)
IDE extension for persistent agent memory
Claims to verify
LM Arena web #1 / Artificial Analysis 57. Both are dated snapshots (LM Arena board is Jul 21 2026, 506k votes); leaderboards change fast. Verify current standings before quoting.
Pricing ($3/$15 vs $5/$30 vs $10/$50). On-screen only for the Claude side; confirm Kimi and GPT numbers on their current pricing pages.
"Vision in the loop". Plausible and consistent with Kimi's vision strength, but stated by the reviewer, not from a Moonshot spec here; verify against Moonshot's docs.
"~3x slower Kimi Code" and "weights aren't open yet". The reviewer's own testing and reading of Kimi's docs; both are time-sensitive (an open-weights release or harness update would change this).
58-gate test / 100+ references. Check against the current Nutlope/hallmark repo; numbers may drift with versions.
Distillation claim (Kimi inherits Opus style). Presented as general knowledge ("Chinese models are known to be trained through distillation"); treat as a hypothesis, not a proven provenance.
Glossary
Kimi K3: Moonshot AI's flagship large language model, strong at front-end/website design, with a 1M-token context window.
Moonshot AI: The company behind the Kimi models.
Harness: The program that runs an AI model and gives it tools, context, and commands (Claude Code, Codex, and Kimi Code are all harnesses).
Kimi Code: Kimi's own terminal-based coding harness, rejected here as too slow.
Claude Code: Anthropic's command-line coding agent; used here to run Kimi K3 instead of Kimi Code.
CLI proxy API / CLIProxyAPI: A tool that turns the coding subscriptions you're logged into into a single local API on your machine, so another harness can call them without a per-token bill.
Base URL: The web address a tool sends its API requests to; overriding it repoints Claude Code from Anthropic's servers to the local proxy.
Auth token: The credential passed with each API request to prove you're allowed to use it.
Vision in the loop: The model taking a screenshot of what it just built and adjusting from the rendered result, rather than guessing from the code alone.
Open weights: When a model's trained parameters are published so anyone can host it; Kimi K3's are described here as not yet open, so only Kimi's servers serve it.
Distillation: Training one model on the outputs of another, which can transfer the second model's style; cited as why Kimi's designs echo Opus.
Hallmark: An open-source anti-AI-slop design skill for agents (Nutlope/hallmark), used through four verbs.
Verb: A named command mode of the skill (default / audit / redesign / study) that loads a specific workflow.
Audit (verb): Scores an existing design against known anti-patterns and returns a ranked punch list without editing anything.
Study (verb): Uses a site you like as a design reference rather than cloning it, so the output stays original.
AI slop: Generic, tell-tale AI design output; here, patterns like Unsplash stock photos, gradient text, rounded boxes, and default fonts.
Anti-pattern: A recurring bad-practice pattern the skill is built to detect and avoid.
Pre-flight: The skill's first step, which scans the existing project (fonts, palette, motion) and decides what to keep versus replace before building.
58-gate test: The set of 58 checks Hallmark runs before returning output, to confirm the design is clean of slop.
Auto-compaction: Claude Code automatically summarising older context when the window fills; it doesn't run when a non-Claude model like Kimi is driving, so context can overflow and answers drift.
Auto-invocation: A skill firing automatically when relevant; unreliable with Kimi because it's tuned to Claude's own models, so you invoke via the slash command instead.
LM Arena: A leaderboard where models compete on the same prompt and are ranked by blind user votes.
Artificial Analysis: A benchmarking service that scores models on an intelligence index and other axes.
Personal recommendations
Proposals for Anthony to accept or reject. Nothing was installed; the brew/GitHub install commands were treated as untrusted.
1
Adopt Hallmark (or its ideas) as an anti-slop gate in site builds
the audit verb produced a severity-ranked report (1 critical / 2 major / 3 minor) naming concrete slop (Geist for both display and body, stock photos as artwork, nav vanishing on mobile), then offered a one-tap fix; across Kimi, Opus, and Codex the skill made output visibly more intentional.
System value
this maps onto the impeccable pipeline and the TheGallery build standard. Even without installing Hallmark, its anti-pattern list (no Unsplash stock, no gradient text, no default fonts, real type pairing, honest imagery) is a ready-made pre-ship checklist.
Proposed form
a reference checklist in the website-build toolkit, and evaluation of Nutlope/hallmark as an installable audit step.
Target project
impeccable-pipeline / TheGallery build standard.
2
CLI-proxy technique to trial Kimi K3 cheaply inside Claude Code
pointing Claude Code's base URL at a local CLIProxyAPI (or Moonshot's direct Anthropic endpoint), passing a local key, and setting ANTHROPIC_MODEL=kimi-k3 runs Kimi K3 in the Claude Code harness on an existing subscription, session-scoped.
System value
a low-commitment way to A/B Kimi K3 against Fable 5/Opus on real design tasks without changing default tooling and without a per-token API bill.
Proposed form
a short tooling note documenting the env-var launch and the two base-URL options, with the "session-only, no auto-compaction, invoke skills manually" caveats.
Target project
computer/tooling docs (a "running non-Claude models in Claude Code" note).
the video catalogues each model's defaults, Opus 4.8 (orange/cream/brown, gradients, rounded boxes, hero-behind, hype words), Kimi (inherits Opus via distillation), Codex (green/white, SVGs, small fonts), and the shared slop tells (Unsplash, gradient text, placeholders).
System value
knowing a model's defaults lets you prompt against them up front, which is faster than auditing after. Useful for any AI-assisted design work Alexana does.
Proposed form
a one-page "model design tells + counter-prompts" reference.
Save the playbook to read later, or hand the raw notes to your favorite AI.
What's this?
The Markdown file (a .md file) is a plain-text copy of this whole playbook, written in the simple format AI chat tools read best. It keeps the headings, links, timestamps, and captions and drops all the page styling. Think of it as the raw notes behind this page, ready to hand to an assistant.
To use it, download the file and drag it into ChatGPT, Claude, or any AI chat (or just paste the text in), then ask for what you want: “Summarize this into a one-page cheat sheet,” “Turn these steps into a checklist I can follow,” or “Quiz me on the key ideas.” Because the file is already structured, the assistant works from the real content instead of guessing.